
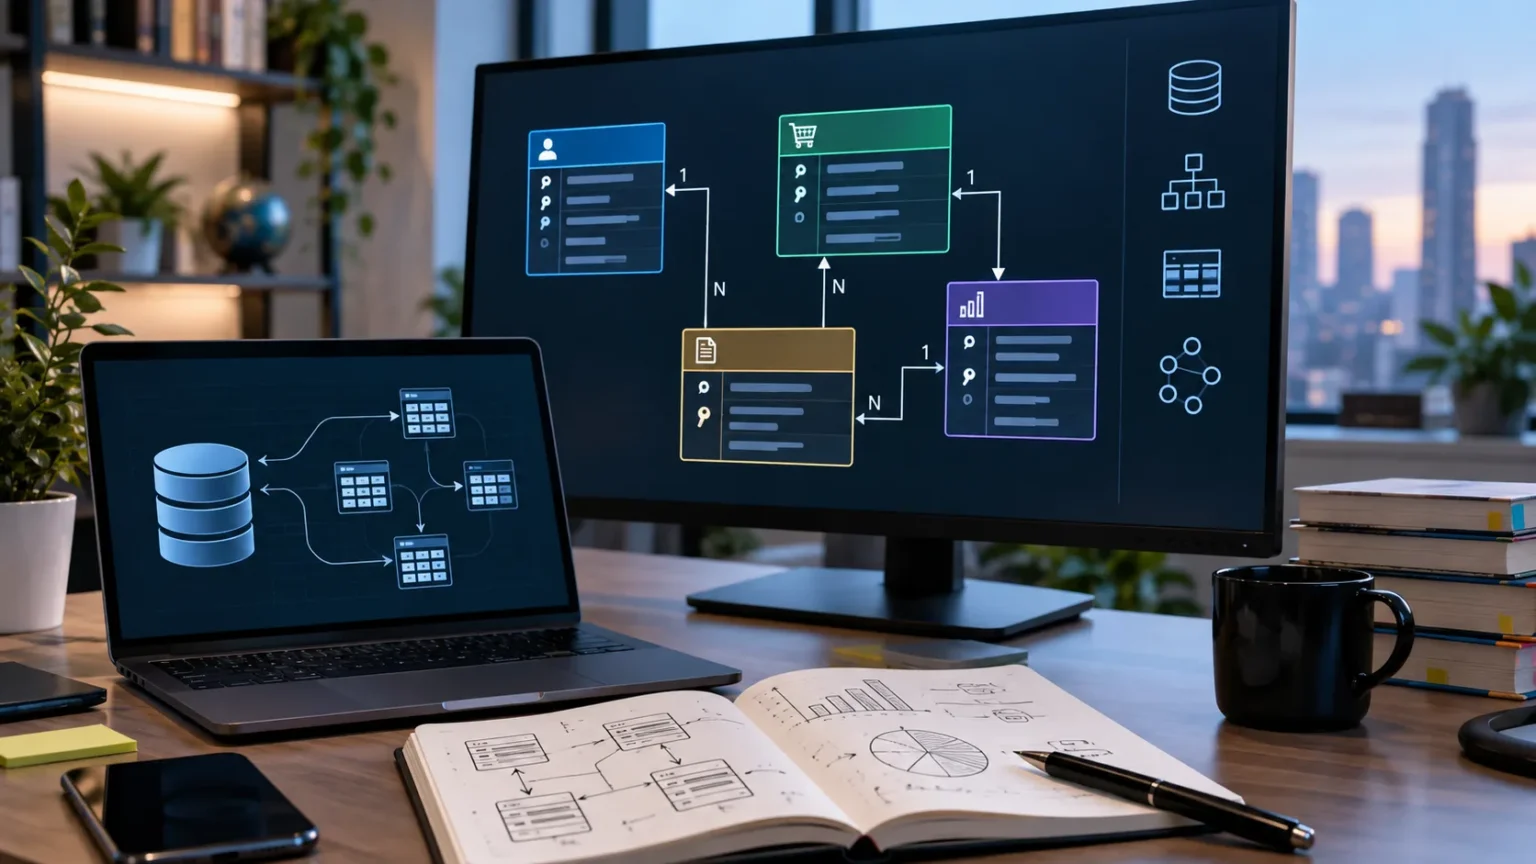
Data modeling is the process of organizing information so it can be stored, connected, understood, and used efficiently. It gives businesses and technical teams a clear blueprint showing how different pieces of data relate to each other. Without a well-designed model, databases can quickly become difficult to manage, especially as the volume and complexity of information increase.
Whether you are building a customer database, analytics dashboard, e-commerce platform, or enterprise data warehouse, data modeling helps create consistency. It improves data quality, simplifies reporting, and reduces confusion between teams. Understanding the different types of data models and how they work is an important foundation for anyone involved in analytics, databases, business intelligence, or data engineering.
What Is Data Modeling?
Data modeling is the process of creating a structured representation of data and the relationships between different data elements. It defines what information exists, how it is connected, and how it should be stored. A data model acts like a blueprint that helps developers, analysts, and business teams understand how information moves through a system.
For example, an online store may need to organize information about customers, products, orders, payments, and shipping. A data model explains how a customer connects to an order, how an order contains products, and how payments relate to transactions. These relationships help ensure the database stores information in a logical and consistent way.
Data modeling can range from simple diagrams to detailed technical structures used inside relational databases and data warehouses. The level of detail depends on the stage of development and the purpose of the system. Most organizations use conceptual, logical, and physical data models to move gradually from business ideas to an actual database structure.
Why Is Data Modeling Important?
Data modeling helps organizations create a common understanding of how information should be organized. Business teams may describe customers, orders, products, or transactions differently, which can lead to confusion. A shared model defines important terms and relationships so everyone involved in a project works with the same structure and meaning.
Another major benefit is improved data quality. Clear rules can define whether a field is required, which values are allowed, and how different records should connect. These decisions reduce duplicate information, inconsistent naming, missing values, and other problems that can make reporting and analysis less reliable.
Good modeling also makes databases easier to maintain and scale. Developers can understand where information belongs, while analysts can identify which tables or fields they need for reporting. As systems expand, a well-designed data structure makes it easier to add new features without creating unnecessary complexity or breaking existing relationships.
What Are the Three Main Types of Data Models?
The three main types of data models are conceptual, logical, and physical models. Each represents data at a different level of detail and serves a different purpose during system development. Together, they provide a structured path from understanding business requirements to creating the actual database that stores information.
A conceptual model provides a high-level overview of important business entities and their relationships. A logical model adds more detail by defining attributes, keys, and relationships without focusing on a specific database technology. The physical model then translates this design into actual tables, columns, indexes, constraints, and technical database structures.
Using all three stages helps prevent teams from jumping directly into technical development before understanding the underlying business requirements. The conceptual model explains what the organization needs, the logical model explains how the information should connect, and the physical model explains exactly how that structure will be implemented within a database system.
Conceptual Data Modeling Explained
Conceptual data modeling focuses on the big picture. It identifies major business entities and how they relate without including technical details such as column names, data types, or database indexes. This makes conceptual models useful during early project discussions when business stakeholders and technical teams need to agree on what information the system should represent.
Consider a university system containing students, courses, instructors, and departments. A conceptual model may simply show that students enroll in courses, instructors teach courses, and departments manage programs. It does not yet specify exactly how student IDs or course codes will be stored inside the database.
The simplicity of conceptual models makes them easier for nontechnical stakeholders to understand. Managers, subject-matter experts, analysts, and developers can review the structure together before detailed development begins. Identifying missing entities or incorrect relationships at this early stage can prevent expensive changes later in the project.
Logical Data Modeling Explained
Logical data modeling adds more detail to the conceptual structure while remaining independent of a specific database platform. It defines entities, attributes, primary keys, foreign keys, and relationships. The goal is to describe how information should logically be organized before deciding whether it will eventually be implemented in PostgreSQL, MySQL, SQL Server, or another technology.
For example, a logical customer entity might contain CustomerID, FirstName, LastName, Email, PhoneNumber, and RegistrationDate. An Order entity could contain OrderID, CustomerID, OrderDate, and TotalAmount. CustomerID would connect the two entities, showing that each order belongs to a particular customer.
Logical modeling is also where normalization and relationship rules become more important. Designers examine whether information has been duplicated unnecessarily and whether each entity represents a clear business concept. A strong logical model provides developers with detailed guidance while remaining flexible enough to work across different database technologies.
Physical Data Modeling Explained
Physical data modeling describes exactly how the database will be built. It converts the logical design into actual tables, columns, data types, primary keys, foreign keys, constraints, indexes, and storage structures. Unlike conceptual and logical models, a physical model is closely connected to the chosen database management system.
For example, the logical attribute RegistrationDate might become a DATETIME column inside a physical SQL database. CustomerID may be implemented as an integer primary key, while Email could receive a unique constraint. Developers may also create indexes on frequently searched fields to improve query performance.
Performance, storage, security, and scalability become important considerations during physical modeling. Database designers must determine how information will be accessed and how the structure will perform as the dataset grows. A technically correct model that performs poorly under real workloads may still require optimization before it is suitable for production.
Common Data Modeling Techniques
Entity-relationship modeling is one of the most widely used approaches for relational databases. It represents entities such as customers, orders, and products while showing the relationships between them. Entity-relationship diagrams, commonly called ERDs, give teams a visual way to understand database structures before implementing them.
Dimensional modeling is another important technique, particularly in data warehouses and business intelligence systems. It commonly organizes information into fact tables and dimension tables. Fact tables store measurable events such as sales, while dimensions provide descriptive context such as customer, product, location, or date information.
Other approaches include hierarchical, network, object-oriented, and document-based modeling. Modern organizations may use different techniques depending on whether they work with relational databases, NoSQL systems, cloud warehouses, or analytics platforms. The best approach depends on the type of information being stored and how users need to access it.
Data Modeling Example for an E-Commerce Store
Imagine an online retailer that needs to manage customers, products, orders, and payments. The conceptual model might include these four main entities and show the basic relationships between them. Customers place orders, orders contain products, and payments are connected to completed or pending transactions.
At the logical level, each entity receives detailed attributes. The Customer entity may include CustomerID, Name, Email, and Address, while Product may contain ProductID, ProductName, Price, and Category. An Order table could include OrderID, CustomerID, OrderDate, and Status, allowing analysts to connect individual purchases with specific customers.
The physical model then converts these entities into actual database tables and columns. Developers select appropriate data types, primary keys, foreign keys, indexes, and constraints to keep the information consistent. Once implemented correctly, the model can support checkout systems, inventory reporting, customer analysis, and sales dashboards from the same organized data structure.
Data Modeling for Analytics and Business Intelligence
Data modeling plays a major role in analytics because analysts need reliable relationships between different datasets. Poorly organized information can result in duplicated calculations, inaccurate totals, or confusing dashboards. A clear analytical model allows users to connect dimensions and metrics without repeatedly rebuilding complicated relationships.
Business intelligence systems often use dimensional models such as star schemas. A central fact table may contain sales transactions, while connected dimension tables provide information about customers, products, locations, and dates. This structure makes it easier for reporting tools to calculate metrics and filter results across different business categories.
Understanding modeling can also strengthen broader analytical skills. Professionals exploring a data analyst career often focus on SQL, spreadsheets, and visualization, but learning how data is structured makes those skills more effective. Analysts who understand relationships between tables can write better queries and build more reliable reports.
Data Modeling vs Database Design
Data modeling and database design are closely related, but they are not exactly the same process. Data modeling focuses on defining information, relationships, and business rules. Database design takes those models and determines how they should be implemented within a specific database environment.
A data model might define that every order must belong to one customer and can contain several products. Database design determines how those relationships will be created using tables, foreign keys, junction tables, constraints, and indexes. The modeling stage explains the structure, while database design focuses more heavily on technical implementation.
Both activities are important because technical decisions should reflect genuine business requirements. Jumping directly into table creation without proper modeling can produce duplicate fields, confusing relationships, or inefficient structures. Starting with a clear model allows database developers to make technical choices based on an agreed understanding of the information.
Best Practices for Effective Data Modeling
Start by understanding the business requirements before creating tables or diagrams. Speak with people who understand the processes, terminology, and reporting needs of the organization. A technically sophisticated model will still fail if it does not accurately represent how the business actually creates and uses information.
Keep naming conventions clear and consistent throughout the model. Similar concepts should not have multiple confusing names, and fields should be descriptive enough for future users to understand their purpose. Documenting important entities, relationships, definitions, and business rules also makes the model easier to maintain as employees and systems change.
Finally, review and test the model using realistic use cases. Ask whether common reports, transactions, integrations, and workflows can be supported efficiently by the proposed structure. Data models should evolve when requirements change, but thoughtful planning at the beginning can significantly reduce unnecessary redesign and long-term maintenance problems.
Common Data Modeling Mistakes to Avoid
One common mistake is creating the model without involving business stakeholders. Developers may understand database technology but lack detailed knowledge about how customers, products, transactions, or other business concepts actually work. Collaboration ensures that the final structure represents real processes instead of assumptions made only from a technical perspective.
Another mistake is storing the same information in several places without a clear reason. Excessive duplication can create inconsistencies when one copy changes while another remains outdated. Proper normalization and clearly defined relationships help minimize unnecessary repetition, although analytical systems may intentionally use some denormalization for performance.
Overcomplicating the model can also create problems. Adding unnecessary entities, relationships, or technical rules may make queries and maintenance more difficult than required. The objective is not to create the most complicated architecture possible, but to build a clear structure that accurately supports current requirements while allowing reasonable room for future growth.
Conclusion
Data modeling provides a structured way to define how information should be organized, related, and stored. It creates a common blueprint that helps business teams, analysts, developers, and database professionals understand the same data environment. Strong models can improve consistency, data quality, reporting accuracy, and long-term system maintainability.
Conceptual, logical, and physical models represent the three primary levels of data modeling. Conceptual models describe the business view, logical models define detailed relationships and attributes, and physical models explain exactly how the database will be implemented. Moving through these stages helps teams solve business requirements before focusing on technical details.
Whether you work in analytics, database development, business intelligence, or data engineering, understanding data modeling can improve how you work with information. Start by learning entities, attributes, keys, relationships, and common modeling techniques. These fundamentals make it easier to understand complex databases and build systems that remain useful as data requirements grow.
FAQs About Data Modeling
What is data modeling in simple terms?
Data modeling is the process of creating a blueprint showing what information a system stores and how different pieces of data connect. It helps teams organize databases clearly before building or expanding them.
What are the three types of data models?
The three main types are conceptual, logical, and physical data models. They move from a high-level business view to detailed relationships and finally to the technical database structure used for implementation.
What is an example of data modeling?
An e-commerce data model may include customers, products, orders, and payments. Relationships show which customer placed an order, which products were purchased, and which payment belongs to the transaction.
Is data modeling important for data analysts?
Yes. Understanding data models helps analysts recognize relationships between tables, write better SQL queries, create accurate calculations, and avoid reporting errors caused by incorrectly joined or misunderstood datasets.
What tools are used for data modeling?
Data professionals can use diagramming, database design, and modeling tools to create ERDs and technical schemas. The specific tool matters less than understanding entities, keys, relationships, constraints, and business requirements.