
Types of Keys in Databases: Primary, Foreign & More
Database keys are one of the most important concepts to understand when working with relational databases. They help identify records, connect related tables, prevent duplicate data, and preserve the accuracy of information as a database grows. Whether you are learning SQL, designing an application, preparing for a database interview, or improving an existing schema, understanding different types of keys in databases gives you a strong foundation. Terms such as primary key, foreign key, candidate key, composite key, and unique key may initially sound similar, but each serves a distinct purpose. Once their roles become clear, database relationships and normalization become much easier to understand.
Modern applications often store information across many interconnected tables instead of keeping everything in one large dataset. An ecommerce system, for example, may contain separate tables for customers, products, orders, payments, and shipping details. Keys tell the database which record is which and how information from one table relates to information in another. Poor key design can lead to duplicate rows, broken relationships, inconsistent updates, and difficult data maintenance. Good database key design, by comparison, supports data integrity, efficient queries, scalability, and clearer application logic. Learning how the different database keys work together is therefore useful for beginners and experienced developers alike.
What Are Keys in a Database and Why Do They Matter?
A database key is one column or a combination of columns used to identify, distinguish, or connect records within relational database tables. Consider a Students table containing thousands of people with names, email addresses, courses, and enrollment information. Names alone may not uniquely identify students because two people can easily have the same name. A dedicated StudentID value can distinguish every student regardless of similarities in their other information. That identifying value is an example of how a database key can provide uniqueness. Keys therefore give database systems reliable ways to locate particular records and maintain relationships between pieces of information.
Keys are especially important because relational databases divide information into separate tables to reduce duplication and improve organization. Instead of repeating a customer’s complete information inside every order record, a database can store the customer once and reference that customer from an orders table. A key connects the two tables so the database knows which customer belongs to each order. This structure reduces redundant information while supporting accurate updates across the system. If the customer changes an email address, the database can update one customer record instead of hundreds of duplicated order entries. Database relationships built with keys are therefore central to effective relational database design.
Another major purpose of database keys is protecting data integrity, which means keeping information accurate, consistent, and logically connected. A primary key prevents multiple records from using the same identifier when uniqueness is required. A foreign key can stop an order from referencing a customer record that does not exist, depending on the defined constraint. Unique keys can prevent duplicate email addresses, usernames, or other values that must remain distinct. These rules allow the database itself to enforce important business requirements instead of depending entirely on application code. Strong database constraints reduce the likelihood that accidental inserts, updates, or deletions will leave inconsistent information behind.
Keys also affect how efficiently applications retrieve and manage information, although a key and an index are not exactly the same thing. Database systems commonly create indexes for primary keys and unique constraints so specific records can be located efficiently. Foreign key columns may also benefit from appropriate indexing when they are frequently used for joins or relationship lookups. Good key choices therefore influence both logical database structure and practical query performance. However, adding unnecessary keys or indexes can increase storage use and make inserts and updates more expensive. Effective database design balances integrity, simplicity, maintainability, and performance instead of adding constraints without understanding their purpose.
Several types of keys can appear in the same table because key terminology describes different logical roles rather than completely separate database features. A column could begin as a candidate key because it can uniquely identify records and then be selected as the table’s primary key. Another candidate key that is not selected becomes an alternate key in traditional database terminology. A key may also be described as natural or surrogate depending on whether its value comes from real-world data or is generated specifically for identification. Understanding these overlapping classifications prevents confusion when studying relational database concepts. The following sections explain the most important types and how each fits into practical database design.
Primary Key: The Main Identifier for Each Record
A primary key is the column or set of columns chosen to uniquely identify every row in a database table. Each primary key value must be unique because two records cannot share the same primary identifier. Primary key columns also cannot contain NULL values because every record needs an identifiable key value. In a Customers table, for example, CustomerID might serve as the primary key while names, telephone numbers, and addresses remain ordinary attributes. Even if two customers share the same name, their customer IDs remain different. This reliable uniqueness makes primary keys one of the central building blocks of relational database systems.
Primary keys should normally be stable because changing an identifier after related records have been created can complicate database relationships. Imagine using a person’s telephone number as a primary key and then discovering that customers regularly change their numbers. Every related record containing that identifier could potentially need to change as well. A generated customer ID is often easier to maintain because it has no business meaning and rarely needs modification. Stability is therefore an important consideration when selecting the primary key from available candidate keys. A technically unique value is not necessarily the best primary key if it changes frequently or contains unnecessary complexity.
A table can have only one primary key constraint, although that primary key may consist of more than one column. When multiple columns jointly form the primary key, the result is commonly called a composite primary key. For example, an Enrollment table might use both StudentID and CourseID to identify each student’s enrollment in a particular course. Neither column alone would necessarily be unique because one student can take multiple courses and one course can contain many students. Together, however, the values may uniquely identify a particular enrollment relationship. Composite keys are especially common in junction tables that model many-to-many relationships between entities.
Choosing the right primary key can make a database easier to scale, maintain, integrate, and query. Common generated identifiers include incrementing integers and universally unique identifiers, often called UUIDs. Integer IDs are compact and straightforward, while UUIDs can be useful in distributed systems where identifiers need to be generated independently without a central sequence. Neither approach is automatically correct for every database architecture, so developers should consider system requirements before selecting one. Primary keys should generally be as simple as practical while remaining reliable throughout a record’s lifetime. Good primary key design reduces unnecessary dependencies between business information and database identity.
Primary keys also play an important role when tables are connected through foreign keys. Once CustomerID uniquely identifies a customer, another table can store that value to indicate which customer owns an order, subscription, review, or payment method. Applications can then join related tables without repeatedly storing the customer’s complete details. The primary key essentially provides a dependable reference point for the entity represented by the table. This makes it easier to enforce referential integrity and reason about relationships throughout the database. For most relational tables representing distinct entities, selecting a clear and stable primary key should be an early part of schema design.
Foreign Key: How Database Tables Connect to Each Other
A foreign key is a column or set of columns that references a key in another table, creating a relationship between the two datasets. Suppose a database contains Customers and Orders tables, with CustomerID serving as the primary key of Customers. The Orders table can also contain a CustomerID column that references the customer table. In that context, Orders.CustomerID acts as a foreign key rather than the main identifier for an order. Multiple orders may contain the same customer ID because one customer can place many orders. This arrangement creates a classic one-to-many relationship while avoiding unnecessary duplication of customer information.
Foreign keys are closely associated with referential integrity, which ensures that relationships between tables remain valid. If an order references CustomerID 105, a foreign key constraint can require a corresponding customer record with that identifier to exist. Without such a rule, incorrect application code might insert orders associated with nonexistent customers. Those disconnected records are sometimes described as orphan records because their expected parent record cannot be found. Foreign key constraints help prevent this type of inconsistency at the database level. They therefore provide valuable protection even when application code already contains validation designed to check relationships before data is inserted.
Database designers also need to decide what should happen when a referenced record is updated or deleted. Relational database systems commonly provide actions such as restricting the deletion, cascading the deletion, setting the foreign key to NULL, or applying another supported behavior. A cascading delete can automatically remove dependent records when the parent record disappears, but it should be used carefully because large chains of related data may be affected. Restricting deletion may be safer when historical records must remain available. The correct choice depends on the meaning and lifecycle of the data rather than on convenience alone. Referential actions should therefore reflect clear business rules.
Foreign keys can also reference columns that are guaranteed to be unique even when those columns are not the table’s primary key, depending on the database system and schema design. However, referencing a primary key is extremely common because primary keys provide stable and unambiguous identifiers. Foreign key columns themselves do not need to contain unique values because many child records may point to the same parent. They may also allow NULL when the relationship is optional, provided the schema permits it. For example, an employee record might contain an optional ManagerID value when some employees do not currently report to another employee. Foreign keys can therefore model both required and optional relationships.
Foreign key design affects query performance as well as integrity because relational applications frequently join tables through these columns. Adding an appropriate index to frequently queried foreign key columns can improve searches, joins, and some update or delete operations. However, developers should evaluate indexing based on actual query patterns instead of assuming every column requires an additional index. The relationship itself remains logically important regardless of whether a separate index is created. Well-designed foreign keys make the database structure easier for developers, analysts, and database tools to understand. They communicate how entities relate while helping the database enforce those relationships consistently.
Candidate Keys, Super Keys, and Alternate Keys Explained
A candidate key is a minimal column or set of columns that can uniquely identify every record in a table. The word minimal matters because removing any column from a candidate key should cause it to lose its ability to uniquely identify records. Consider an Employees table where both EmployeeID and a guaranteed unique company email address can identify a specific employee. Each could qualify as a candidate key if the database rules ensure its uniqueness and required values. One candidate key is eventually chosen as the primary key, while the others remain potential unique identifiers. Candidate keys therefore represent the valid choices available when deciding how records should be identified.
A super key is broader than a candidate key because it is any set of columns capable of uniquely identifying a row, even when some included columns are unnecessary. If EmployeeID alone uniquely identifies an employee, then EmployeeID is already sufficient for identification. Combining EmployeeID with LastName would still uniquely identify the employee because the unique ID remains present. That combination would therefore be a super key, but it would not be minimal. Candidate keys can consequently be viewed as minimal super keys without redundant attributes. Understanding this distinction is particularly useful in database theory, normalization exercises, academic coursework, and technical interviews where precise terminology matters.
An alternate key is generally a candidate key that was not selected to become the primary key. Suppose a Users table contains both a generated UserID and a unique email address. If UserID becomes the primary key, the email address may be treated conceptually as an alternate key because it can still uniquely identify a user. In an actual SQL database, that alternate key may be implemented using a UNIQUE constraint rather than a feature literally named alternate key. The terminology therefore describes its logical role more than a universal SQL syntax. Alternate keys remain important because applications may need to look up records through meaningful unique values besides the primary identifier.
The relationship between super keys, candidate keys, primary keys, and alternate keys becomes easier to understand when viewed as a selection process. First, identify all column combinations capable of uniquely identifying a record, which produces potential super keys. Next, remove unnecessary attributes until only minimal combinations remain, giving you candidate keys. One candidate key is then selected as the primary key based on factors such as stability, simplicity, size, and maintainability. Other candidate keys become alternate identifiers that should usually retain their uniqueness rules. This logical process helps database designers distinguish between values that merely happen to be unique today and values that are guaranteed to remain unique by design.
Candidate key analysis can also expose hidden problems in a schema before they become difficult to fix. A developer might initially assume an email address can permanently identify a customer, only to learn later that the system allows email changes or account sharing. Similarly, a product code may appear unique until multiple regions use the same coding system. Understanding the business rules behind each candidate identifier is therefore essential. Database uniqueness should be based on explicit guarantees rather than assumptions made from a small sample of existing data. By carefully identifying candidate and alternate keys, designers can choose primary keys that remain dependable as applications and datasets evolve.
Composite Keys and Unique Keys in Database Design
A composite key consists of two or more columns that work together to uniquely identify a record. This approach is useful when no single attribute provides enough information to distinguish every row or when the combination naturally represents a relationship. Consider an OrderItems table connecting products with customer orders. An order can contain many products, and a product can appear in many different orders. The combination of OrderID and ProductID may uniquely identify each product within an order, assuming a product appears only once per order. In that situation, those two columns can form a composite key that captures the logical relationship directly.
Composite keys frequently appear in junction tables used to model many-to-many relationships. A university database might contain separate Students and Courses tables, with an Enrollments table connecting them. StudentID alone cannot uniquely identify an enrollment because each student can join multiple courses. CourseID alone also cannot identify one enrollment because many students can take the same course. Combining StudentID and CourseID, however, can prevent duplicate enrollment records for the same student-course pair. This structure is both logical and efficient for many straightforward relationship tables. Additional columns such as enrollment date, grade, or status can then describe the relationship without becoming part of the identifying key.
Composite keys can become less convenient when many other tables need to reference them because every related table may need to store all key columns. Longer keys can also make queries, indexes, joins, and application code more cumbersome. For this reason, some database designers introduce a surrogate primary key, such as EnrollmentID, while separately adding a unique constraint to the natural column combination. That approach provides a simple identifier while still preventing duplicate student-course relationships. Whether this is beneficial depends on how the table is used and referenced elsewhere. Composite keys are not inherently bad, but their practical maintenance costs should be considered alongside their logical advantages.
A unique key or unique constraint ensures that duplicate values are not allowed within a particular column or combination of columns. A Users table might use UserID as the primary key while requiring Username and EmailAddress to remain unique. These additional uniqueness rules protect important business data without making those columns the primary key. SQL database systems differ in how they handle NULL values within unique constraints, so implementation details should be checked for the chosen platform. Unlike a primary key, a table can normally contain multiple unique constraints. This makes unique keys valuable for enforcing several independent forms of uniqueness within the same entity.
Primary keys and unique keys therefore share the goal of protecting uniqueness, but their roles are not identical. The primary key is the main identifier chosen for each row and generally cannot contain NULL. Unique constraints provide additional protections for other columns that should not contain duplicate values. A table might consequently have one primary key and several unique constraints serving different business requirements. Understanding this distinction helps developers avoid using a primary key simply because a column needs uniqueness. Good schema design assigns the primary identity deliberately while using unique constraints wherever additional data must remain distinct.
Natural Keys and Surrogate Keys: Which Should You Use?
A natural key is an identifier derived from meaningful data that already exists in the real-world domain represented by the database. Examples might include a standardized product code, government-issued identifier, country code, or another business value that is guaranteed to be unique. Because natural keys carry meaning outside the database, they can sometimes make data easier for people to understand. A product identified by an established code may not require a separate generated number simply to distinguish it from other products. However, natural keys are useful only when their uniqueness and stability can genuinely be trusted. Business values that change frequently can become problematic identifiers even when they are currently unique.
A surrogate key is an artificial identifier created specifically for database use rather than taken from business data. Common examples include auto-incrementing integers, identity columns, sequences, and generated UUID values. A CustomerID such as 81425 may have no meaning to customers or staff, yet it provides a stable way to identify the associated database record. Surrogate keys are popular because they separate database identity from business attributes that may change over time. A customer can change a name, email address, phone number, or company without requiring the primary identifier to change. This stability can simplify relationships across large numbers of dependent tables.
Surrogate keys also help when the natural identifier would otherwise contain several long columns. Imagine an entity whose natural identity depends on country, region, account type, and customer number together. Using that multi-column value as the primary key could make every referencing foreign key significantly larger and more complex. A generated surrogate ID may simplify joins and application logic while a unique constraint preserves the natural business combination. This pattern allows the database to maintain business uniqueness without forcing every related table to carry a complicated key. It can be particularly useful in large systems where an entity is referenced from many locations.
Natural keys still have important advantages when the underlying identifier is truly stable, compact, and universally recognized. A separate generated ID may add unnecessary complexity when an existing code already satisfies every requirement for a reliable primary key. Natural identifiers can also make some imports, exports, integrations, and troubleshooting tasks easier because the key itself has understandable meaning. Surrogate keys, by comparison, usually require additional columns when records must be matched with external systems. The choice should therefore depend on the domain rather than a rule claiming one approach is always superior. Database architecture benefits most when the reason behind the chosen identifier is explicit and documented.
Many practical schemas use both approaches instead of treating natural and surrogate keys as mutually exclusive alternatives. A surrogate ID can become the primary key while one or more natural business identifiers receive unique constraints. For example, a Products table may have a generated ProductID as its primary key while maintaining a unique manufacturer SKU where business rules require it. This design provides stable internal relationships without sacrificing real-world uniqueness. It also protects the system if a natural identifier later needs to change while still preventing accidental duplicates. Combining surrogate identifiers with properly constrained natural values is therefore a common and flexible pattern in modern relational database design.
How Different Types of Database Keys Work Together
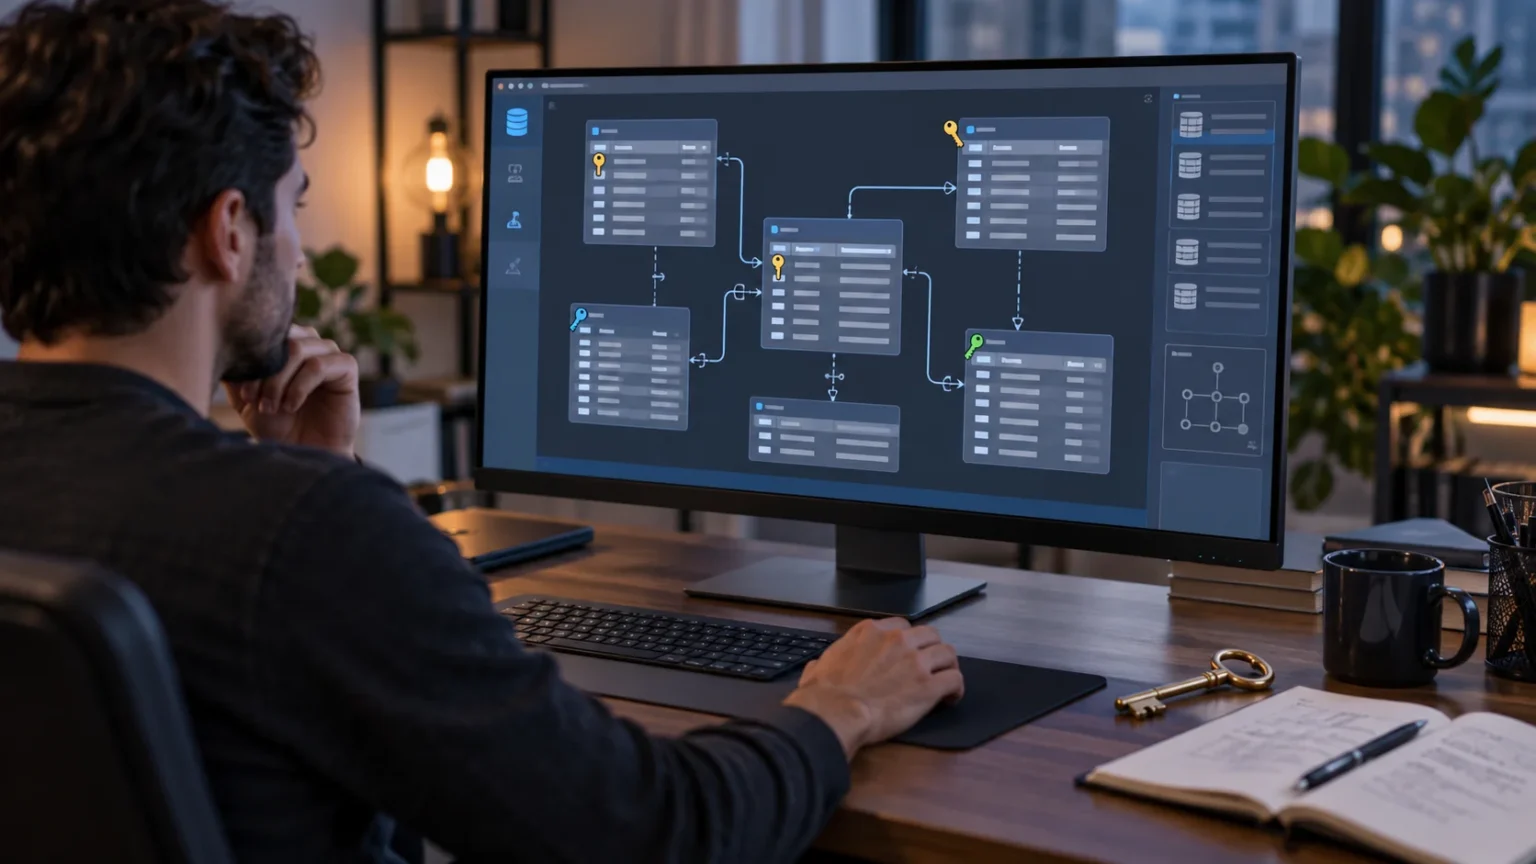
Understanding individual key definitions is useful, but database design becomes much clearer when you see how several keys work together in the same application. Imagine an ecommerce database containing Customers, Orders, Products, and OrderItems tables. CustomerID, OrderID, and ProductID could each serve as primary keys within their respective tables. The Orders table could contain CustomerID as a foreign key linking each order to a customer. The OrderItems table could contain both OrderID and ProductID as foreign keys connecting orders with products. Together, these keys create a relational structure without unnecessarily repeating customer and product information.
Candidate and alternate keys can provide additional protection within that same ecommerce database. A customer’s email address may qualify as a candidate key if the business requires every account to use a unique email. If the generated CustomerID is selected as the primary key, the email can remain an alternate identifier enforced through a unique constraint. Products may similarly have a unique SKU in addition to their internal product ID. These rules allow the application to identify records using useful business information while maintaining stable internal keys. The database therefore uses multiple key types simultaneously because each solves a different integrity or relationship problem.
Good key design also supports database normalization by allowing information to be separated into logical entities without losing connections between them. Instead of placing customer name, email, address, order details, and product information inside every order row, each subject can be stored in its own table. Primary keys identify those independent entities, while foreign keys reconnect them whenever a query requires combined information. This reduces repeated data and helps prevent update anomalies where one duplicated value changes but another copy remains outdated. Keys do not perform normalization by themselves, but they are essential to creating normalized relational structures. Clear relationships also make future schema modifications easier to manage.
Developers should avoid selecting keys based solely on whatever data happens to look unique during initial testing. A table containing only ten users may currently have ten different first names, but that does not make first name a reliable candidate key. Similarly, telephone numbers, addresses, and display names often change or repeat even if the first version of the dataset does not show duplicates. Key decisions need to reflect long-term business rules and expected application behavior. Constraints should then enforce those rules at the database level wherever practical. Designing for guaranteed uniqueness rather than accidental uniqueness prevents problems as thousands or millions of additional records are eventually added.
The best database key strategy is usually simple, explicit, stable, and aligned with how the data is actually used. Choose a dependable primary key for every entity that needs clear identity, use foreign keys to enforce important relationships, and apply unique constraints to additional attributes that must not duplicate. Use composite keys when the combination naturally represents identity, but consider surrogate keys when composite identifiers become difficult to reference throughout a system. Revisit key choices when business rules change rather than assuming the original schema will remain correct forever. Thoughtful key design creates a database that is easier to understand, safer to modify, and more reliable as an application grows.
Common Database Key Mistakes and Best Practices
One common database design mistake is using a value as a primary key simply because it appears unique at the moment. Email addresses, usernames, phone numbers, and other business information may change as application requirements evolve. If many tables reference one of those values, changing it can become considerably more complicated than updating a normal attribute. Before choosing a natural primary key, determine whether the organization truly guarantees its uniqueness and stability throughout the record’s lifetime. If that guarantee is weak, a surrogate key may provide a safer long-term identity. Business values can still receive unique constraints when duplicates need to be prevented.
Another mistake is assuming application-level validation makes database constraints unnecessary. An application may check whether a username already exists before inserting a new account, but another application, import script, administrator, or concurrent request could bypass that particular validation path. A database UNIQUE constraint provides a final layer of protection regardless of which process writes the data. Foreign key constraints similarly prevent invalid relationships even when data arrives from multiple sources. Application validation remains useful for providing friendly error messages and guiding user behavior. However, important integrity rules are usually stronger when the database itself also understands and enforces them.
Overusing composite keys can make a schema difficult to work with when those keys spread through many layers of related tables. A two-column composite key may be perfectly reasonable in a small junction table, but a four-column business identifier referenced by numerous tables can create bulky indexes and complicated joins. This does not mean developers should automatically replace every composite key with an artificial ID. Instead, they should consider how often the key will be stored, joined, updated, and exposed through application interfaces. A surrogate primary key combined with a unique business constraint can sometimes provide a cleaner compromise. The choice should follow practical relationship patterns instead of stylistic preference.
Ignoring foreign key behavior during deletion is another source of unexpected database problems. Developers may add relationships without considering what should happen when a customer, project, category, or other parent record is removed. Automatically cascading every deletion can destroy valuable dependent information, while restricting every deletion can make legitimate cleanup unnecessarily difficult. Some relationships may require soft deletion or historical retention instead of physical removal from the database. Referential actions should therefore be selected according to the lifecycle and meaning of each related record. Testing deletion scenarios before deployment can reveal consequences that are easy to miss when focusing only on inserts and queries.
Finally, key names and conventions should remain understandable to people who will maintain the system later. Consistent names such as CustomerID, OrderID, and ProductID make relationships easier to recognize than unpredictable naming patterns across tables. Database documentation should explain unusual composite keys, natural identifiers, cascading rules, and uniqueness assumptions when their purpose is not obvious. Constraints should also have meaningful names where the database platform allows it, making errors easier to diagnose. Clear key design reduces the mental effort required to understand a schema during debugging, analytics, migration, and development. A well-designed key is therefore not only technically correct but also understandable to the humans working with the database.
Frequently Asked Questions About Types of Keys in Databases
What is the difference between a primary key and a foreign key?
A primary key uniquely identifies each record within its own table, while a foreign key references a key in another table to create a relationship. Primary key values must be unique, whereas multiple foreign key rows can usually contain the same referenced value.
Can a table have more than one primary key?
A table can have only one primary key constraint, but that primary key may contain multiple columns. When several columns together form the primary key, it is known as a composite primary key.
What is the difference between a candidate key and a primary key?
A candidate key is any minimal set of columns capable of uniquely identifying a row. One candidate key is chosen to become the primary key, while the remaining candidate keys are generally considered alternate keys.
What is a composite key in a database?
A composite key uses two or more columns together to uniquely identify a record. It is commonly used in junction tables where neither foreign key alone can uniquely represent a relationship.
Is a surrogate key better than a natural key?
Neither type is automatically better in every situation. Surrogate keys provide stable database-generated identifiers, while natural keys can work well when an existing business value is genuinely unique, compact, and unlikely to change.